
Modernization Monday is a field guide to what it actually takes to modernize your infrastructure for AI, published every other Monday. Each installment takes one piece of the puzzle and breaks it down in plain terms. This is post three of a theoretical twelve. (Twelve has held strong for a solid two weeks now. Who’s betting the over?).
Last time, we followed the GPU from Quake III Arena to a 4,000-pound rack with the appetite of a hippo.
We also started building a vocabulary. A model is a software machine that needs the right GPU hardware to run. Models can have billions of dials we call weights. Training sets the dials. Inferencing runs work through them. Fine-tuning nudges them so they work juuuuust right. Open-weights models are the ones you can run yourself and tweak. You are now conversant in AI, tokenomics, and the model and GPU basics. Now someone pops into the conversation, says they are interested in the tech, and may need to buy something. How do we go about choosing a platform?
Alongside this post, a companion Deep Dive works two sizing examples, heavier on the bits and bytes, for the techies out there. Yes, that makes it an extra post. No, it doesn’t count.
Anatomy of a GPU, for buyers
To choose a GPU, you do not need to read a spec sheet cover to cover, although it helps to have spec-sheet-reading people around on occasion. I work with a few of them. They keep me from running with scissors.
Four categories usually cover the decision of which GPU to use for which model: memory, precision, interconnectivity, and power. Say those four aloud a few times so they stick. We are going to keep coming back to them.
Memory
Let’s start with memory. Gimme some of them good, old-fashioned gigabytes. For a workload to perform well, the model that runs it needs to fit in the memory of the GPU. Yes, GPUs have their own memory, separate from the server’s. Similar function, not the same thing. Picture our builder from the tokenomics post. Memory is the workbench, and every tool for the job should be on the bench before the work starts. If the bench is too small, the carpenter spends all day walking to the truck for the router, putting it back to get the sander out, then back again for the saw. Where did I put my level again? Work gets done at turtle speeds, and every one of those trips is a wasted cycle. In computing, the walk to the truck is called “swapping,” where pieces of the model are shuffled in and out of memory on the fly.
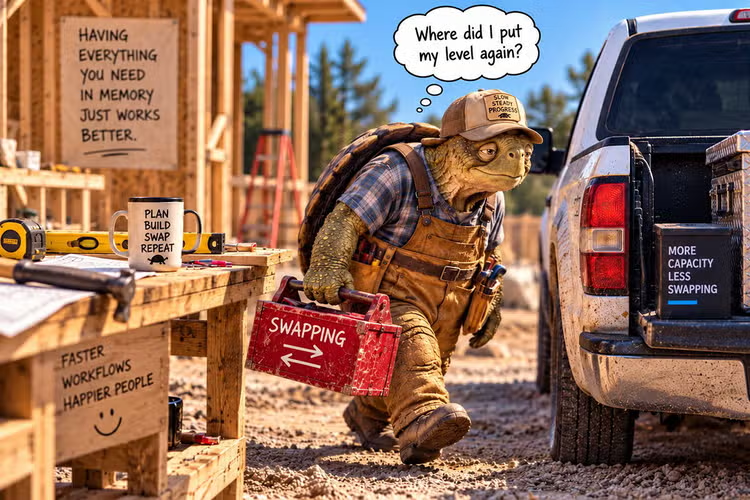
Swapping is slow, and we don’t want it. In almost every case, we want a model to fit in the memory of a GPU. Modern data center GPUs use high-bandwidth memory (HBM) that sits right next to the processors. You buy for capacity, and then the memory’s bandwidth decides how quickly the chip can feed what is stored there to the processors. The machine works at its best when every dial setting is loaded at once, so the weights should fit before anything else matters. Then think of working memory like the notes a machine keeps about a job currently on the assembly line, like a conversation in progress. More simultaneous jobs, or more complex jobs, mean more notes, and more notes mean more memory. Size so the entire working set fits, and performance goes swimmingly.
Do models often span across multiple GPUs? For inferencing, think of loading an entire model into a GPU as the industry default and then you scale by adding more servers and GPUs. Alas, the biggest open models of today’s world simply won’t fit on a single GPU. There is tensor parallelism and pipeline parallelism and and and … Let’s not go there yet. We are still at the basics. Just remember that this situation is what the NVL8 and NVL … oh… wait. We aren’t to the interconnectivity section yet either.
Just remember this, there are use cases where it just makes sense to span GPUs but don’t do it needlessly. DeepSeek, Qwen’s larger MoE variants, Llama 4 are almost always multi-GPU.
Precision
Next comes precision. Each dial of a specific model has a precision measured in bits; a 1 or a 0. Yes, those bits. The more bits you have, the more positions there are on a dial. A 4-bit dial has 16 positions. A 16-bit dial has 65,536. A 64-bit dial has over 18 quintillion, which is 264 or 18,446,744,073,709,551,616 if you don’t have your TI-85 handy. To put this number in perspective, the commonly quoted estimate of grains of sand on Earth’s beaches and deserts is 7.5 quintillion. Luckily, most jobs do not need the dial set to the nearest grain of sand. GPUs do arithmetic at several levels of precision, from 64-bit double precision all the way down to 4-bit formats. Lower precision means more operations per second, and less memory needed per number. Training wants more precision than inferencing. In practice, it runs what is called mixed precision: 16-bit math for the heavy lifting, with 32-bit bookkeeping on the side so the dials don’t drift while they are being turned. Some classic HPC simulations want the most, full 64-bit, and any less just. will. not. do.
Precision versus speed is a classic trade-off in technology, and more of either isn’t always what you need. Jobs and tools can look remarkably similar and still need different precision. Flu shot? Give me the needle quick, and anywhere on my shoulder is fine. I’ve got places to go and children to feed. Injection in my lower back? Doctor, please take all the time you need. I’ll order pizza for the kids.
When you see those fancy performance numbers (“petaflops”) being shown off on stage, they are almost always measured at 4-bit or 8-bit precision, because the fewer bits per dial, the more dials the chip can process per second. They also frequently assume sparsity, which means the chip is allowed to skip dials that are set to zero, and that assumption alone can double the headline number on paper. Your model may or may not have those zeros to skip. Two chips quoted in petaflops cannot be compared until the numerical format and the sparsity assumption on both spec sheets match.
One more spec-sheet word while we are here. I forgot it last time, and nobody will let me edit a posted installment. Remember the stadium full of students from Part One doing simple arithmetic at scale? Most of a GPU is that stadium. One section of it, the tensor cores, does nothing but multiply whole grids of numbers in a single step, which is exactly the math a model’s dials demand, and it does its best work at low precision. When a spec sheet or a keynote quotes petaflops, it is almost always quoting the tensor cores at 4-bit or 8-bit, usually with sparsity. The 64-bit math a demanding scientific simulation needs runs nowhere near that rate.
Again, Inferencing workloads typically don’t need big precision numbers. Training usually runs mixed. HPC is greedy as a pig (new animal *check*). As we said in the tokenomics post, the GPU doesn’t know whether it is folding a protein or finishing your email to your boss. The email is perfectly happy at 8 bits. The protein, as it turns out, is often fine at 16, because modern protein folding is itself an AI model. The climate model or the structural analysis running down the hall, though, wants the full 64. “Why am I not getting the advertised petaflops for my scientific simulation?!” That is why. Someone’s petaflop was measured at someone else’s precision, with someone else’s sparsity assumption. Read the fine print. Details matter.
Also, please note that “precision” and “consistency” are not the same thing. I have no idea why they are constantly getting confused. My dad had a saying about consistency and precision that he repeated to me constantly. It isn’t appropriate for print, so we’ll use a dartboard for color instead.
Interconnectivity
On to interconnectivity. Think of a GPU plugged into a PCIe slot in a server. If you don’t know what a PCIe slot is, go find one of those spec-sheet-reading people. Now think of two GPUs in two different slots. Each one, if sized correctly, can hold a model and work on its own for an inferencing use case, and two GPUs can handle more inferencing connections than one. Each GPU has a capability of its own.
But what if you have a workload that requires multiple GPUs to work together, constantly passing notes at high bandwidth and with very low latency? What we’ve got here is a failure to communicate. Deep cut. First one to name it in the comments wins. Anyone? Now, let’s go back to the students, bring them indoors, and seat them. Picture a room with 32 tables. Each table has 8 chairs and a student in each chair. Now say the room is working on a problem together. The students at the same table can quickly pass notes by hand. If a job requires more than 8 students, you need runners to carry notes to other tables so the students can keep working. If the table is all the way across the room, even a fast runner is slower than a note passed by hand at the same table.
In this analogy, the student is the GPU, the runners are the network (that gets its own installment), and the tables are GPU servers leveraging a technology called NVLink. The “NV” stands for NVIDIA really liking those letters. The “Link” stands for link. No heavy lifting was done in the naming of this technology. NVLink is a high-speed, private connection between GPUs within a server and, as we will see next time, across an entire rack. It has a partner called NVSwitch, which is exactly what it sounds like: a switch chip inside the server that gives every GPU a direct, full-speed path to every other GPU, rather than a daisy chain where notes hop from neighbor to neighbor. NVLink is the wire. NVSwitch is the table everyone sits around. A server called an NVL8 has 8 GPUs connected this way, and every GPU can reach into another GPU’s memory far faster than any network allows. It is still slower than a GPU reading its own HBM, which is why the glove-fitting rule from the memory section stands. An NVLink domain is defined by how many GPUs can talk this way. Outside of an NVLink domain, GPUs communicate over a network, which is an order of magnitude slower. Remember the architect in the tokenomics post who did not want to be responsible for wasting $7,000,000 because the GPUs couldn’t talk to each other fast enough? This is what the architect meant.
All of that was an exceedingly long way to state that if a workload needs GPUs to communicate at high speed, you need to pick GPUs with the connectivity to match. Now that I think about it, maybe I should have started with that... and ended with that.
I can’t quite let the “NV” joke slide without background. I am unapologetically hard-wired like this. “NVIDIA” apparently is derived from the Latin word for envy, “Invidia.” Apparently, the cofounders used it for shorthand to replace “next version” on their early projects. That is the rumor. Is it true? No clue. I never met the cofounders and never worked at NVIDIA. Maybe they will stumble across this and post it in the comments.
Power
Lastly comes power. Bring the electrons to the party.
Every GPU server in a data center has a rated power draw, the number of watts it consumes and turns into heat under load, usually published as a maximum and an average. Most NVL8 servers built on current GPUs like the NVIDIA B300 pull a maximum of roughly 14 to 15 kW depending on configuration, weigh 300 lbs. or more, and put out somewhere between 48,000 and 51,000 BTU per hour of heat. (One kilowatt in becomes about 3,412 BTU per hour out. Every time. Physics does not negotiate. Lisa! In this house, we obey the laws of thermodynamics! Another deep cut.) For perspective, a typical American home averages about 1.2 kW of continuous draw, so one GPU server at full tilt draws as much as a dozen homes. A giant panda weighs about 300 lbs. and spends about 12 hours a day eating. A GPU server weighs the same and eats electrons all 24, with no nap. It draws power whether it is running a job or not. No, they do not turn off when idle. Yes, I get asked that a lot. A typical home’s 3-to-4-ton central air system handles 36,000 to 48,000 BTU per hour, so one GPU server generates at least the heat of an entire house, and the facility has to reject it.
Last time the rack was a hippo. This time the server is a panda. This series is turning into a zoo, which is fair, since the introduction warned that “AI” tells a technologist about as much as “animal” tells a zookeeper.
Can I buy something now?
Not yet, but you can understand the spec sheet, which is more than most buyers can say. Memory decides whether the model fits and for how many people. Precision decides how much of the advertised performance applies to the job. Interconnectivity decides whether GPUs can work together as one machine. Power decides what the facility has to deliver and carry away. In the companion Deep Dive, we put those four numbers to work on a real open-weights model, once for inferencing and once for fine-tuning. Rubber, meet road.
Two of the questions we opened with last time are now answered: which GPU, and what size. Still on the board: how many, from whom, where it goes, and whether you can power it on. Ginger or Mary Ann remains unresolved and probably always will. If you are still in debate about the wind at Wrigley, you may have a problem and should seek help.
Think big. Start small. Fail fast. Discipline matters.
If your team is working through this right now, it is exactly the kind of conversation we have every day. Get in touch and we can talk through where you are.
Between installments: a Deep Dive for the engineers. Two GPU sizing problems, worked by hand.
Next time: Compute, part one. What the GPU goes in: nodes, racks, rows, and who builds them.